Key Notes
- Vitalik Buterin supports reducing dangerous AI capabilities while warning that broad identity checks and surveillance could undermine access to useful models.
- Moonshot reports that Kimi K3.1 Pro scored 81.0% on an internal exploit benchmark against 90.5% without its training-data restrictions, measured over three attempts.
- The safeguards reduce a company-reported test score but do not remove cybersecurity capabilities, and the model’s downloadable weights remain a planned release.
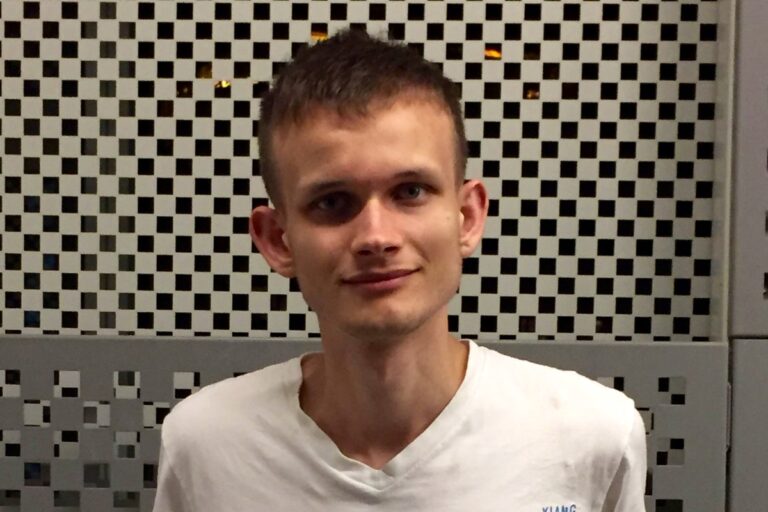
Ethereum co-founder Vitalik Buterin has backed Moonshot AI’s decision to deliberately reduce the offensive cybersecurity capabilities of Kimi K3.1 Pro. His argument is that limiting dangerous uses can help preserve broad access to powerful AI, rather than reserving it for users with approved identities or credentials.
In an October 26 post, Buterin said the world needs time to harden systems, examine legacy software and formally verify new code before more powerful AI-driven attacks arrive. He warned that mishandling the first wave of risks could encourage closed models, universal identity checks and intrusive surveillance.
Discriminating against use cases is MUCH less bad than discriminating against users.
What Moonshot Removed From Kimi’s Training
Moonshot’s technical report says it identified and removed cyber-related material from both its mid-training data and reinforcement-learning environments, while retaining general-purpose coding tasks. The aim was to avoid distributing model weights that push the highest available offensive cyber capability further.
On the company’s internal xdev-bench-hard evaluation, the final K3.1 Pro scored 81.0%, compared with 90.5% for a checkpoint trained without those risk-reduction measures. The 9.5-percentage-point gap refers to pass@3, or success within three attempts, rather than a single-attempt result. These are company-reported figures, not independently reproduced findings.
The benchmark presents source-code vulnerability tasks in controlled environments. A lower score on that test does not establish an equivalent reduction in real-world attacks, and 81.0% does not mean the model has lost its ability to exploit software. Moonshot itself says improved coding and debugging still transfer to cybersecurity tasks after filtering.
Our coverage of Kimi’s launch examined its broader coding improvements and planned release of model weights by November 4. That future release is central to this debate: downloadable weights would let outside developers operate the model on infrastructure they control.
Why Buterin Sees Access Restrictions as a Different Risk
Buterin’s warning concerns what could happen politically if powerful AI attacks outpace defensive preparation. He described a possible hierarchy in which access depends on a person’s nationality or credentials, with some people effectively becoming lower-tier users. This was a warning about a potential outcome, not a claim that Moonshot has announced such a system.
His position also leaves room for a capable model to help maintainers inspect their own software. There is a practical tension here: reasoning about a vulnerability can support a repair, but can also help someone exploit it. Separating those uses through training is a more difficult problem than simply removing a product feature.
The concern about access fits his earlier argument that AI power concentration deserves scrutiny alongside the capabilities of the models themselves. A restriction can reduce one risk while creating another if it makes a small group of providers the gatekeepers for important technical work.
Capability Limits and Containment Address Different Problems
Moonshot’s approach concerns what a model learns before release. Infrastructure controls address what an agent can reach while it is running. In its recent security update, OpenAI described offline web environments and overlapping safeguards for internal frontier research, including tests of unauthorized communication between agents.
As we reported, that policy concerns internal training rather than the removal of browsing from ChatGPT. The comparison illustrates why restricting knowledge, restricting tools and restricting users are distinct choices: each changes a different part of how a model can be used.
Buterin’s endorsement does not settle whether Moonshot’s particular filter is sufficient. The unresolved test is whether defensive teams can gain useful assistance while offensive capabilities spread slowly enough for software and infrastructure to improve. Independent evaluations and the behavior of the eventual downloadable model would provide stronger evidence than a single internal score.
Disclaimer: AIstify is an independent media brand owned and operated by NuvexMedia LLC, publishing news, research, and insights on artificial intelligence, emerging technologies, automation, and related industries. NuvexMedia LLC invests in and collaborates with companies across the AI, technology, software, and digital innovation sectors. These relationships do not influence AIstify’s editorial coverage, and the publication maintains full editorial independence to provide accurate, timely, and objective information. © 2026 NuvexMedia LLC. All rights reserved. This content is for informational purposes only and should not be considered legal, tax, investment, financial, or other professional advice.