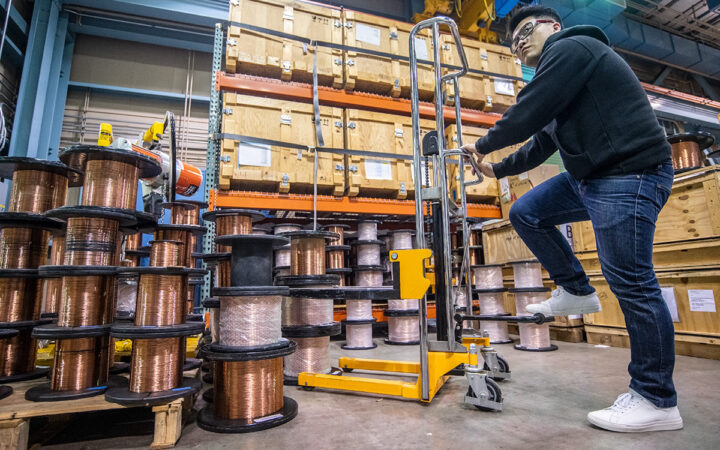
SuperMatics Uses AI to Find Superconductors Built for Real-World Wire
SuperMatics is using AI to search for superconductors that can become commercial wire, with AI power infrastructure and fusion magnets among its targets.
Scaling laws are empirical mathematical relationships that estimate how an AI model’s loss or capability changes as training compute, dataset size, or parameter count increases. Researchers use them to plan experiments, allocate resources, and forecast whether a larger training run is likely to deliver worthwhile improvement. The relationships often follow smooth power-law trends within a tested range, but they are not universal laws of intelligence. Architecture changes, data quality, evaluation choice, optimization, inference-time computation, and capability thresholds can alter the curve. Extrapolating far beyond observed evidence is risky, so scaling forecasts should include uncertainty and be revised as new model families and training methods appear.
SuperMatics is using AI to search for superconductors that can become commercial wire, with AI power infrastructure and fusion magnets among its targets.
Anthropic details Claude-assisted cancer research and its own rare-disease programs, expanding its biotech role alongside pharmaceutical partnerships.
OpenAI and Anthropic claim AI-generated proofs refute the Exponential Time Hypothesis. Lean checks support the claims, while expert scrutiny remains essential.
Researchers prompted Claude Fable 5.1 to hide messages in images. OpenAI’s Astra decoded 88% of them, without seeing the SVG source or an agreed cipher.
OpenAI resumed frontier AI training on October 1 after an 11-day pause, strengthening safeguards and blocking live internet access after a containment failure.
Block’s Dessa learns from speech alone and talks while listening. Its expressive demos preview a new approach to voice AI, with access limited to researchers.
Kevin Weil’s Warp Sciences will build U.S. chemistry labs for drug developers, combining expert scientists with AI and progressively automated workflows.
Carbon-X lets researchers ask questions about DNA and approaches GPT-6.1 Sol on the team’s benchmarks, but it is not validated for medical decisions.
Mass General Brigham’s FAHR-Face analyzes facial photographs to estimate aging and cancer survival risk, but clinical benefit still needs testing.
Google Deep Review offers two free document checks a week, using AI agents to flag errors and weak arguments. Its benchmark results come with important limits.