AI’s ‘Tokenizer Tax’ Can Make Non-English Text More Expensive
Russian text used about 42% more tokens in one test, while a wider study found a 17x gap between languages. Results depend on the tokenizer.
BLEU, or Bilingual Evaluation Understudy, is an automatic metric originally developed for machine translation. It compares short sequences of words in generated text with one or more reference translations, combines precision across several n-gram lengths, and applies a penalty when output is too short. BLEU is inexpensive and useful for comparing systems on the same dataset, but it does not directly measure factuality, fluency, meaning, or human preference. Valid alternative wording can receive a low score, while awkward text can match many reference phrases. Results depend on tokenization and implementation, so reporting should include the exact evaluation settings and, when possible, human judgment.
Russian text used about 42% more tokens in one test, while a wider study found a 17x gap between languages. Results depend on the tokenizer.
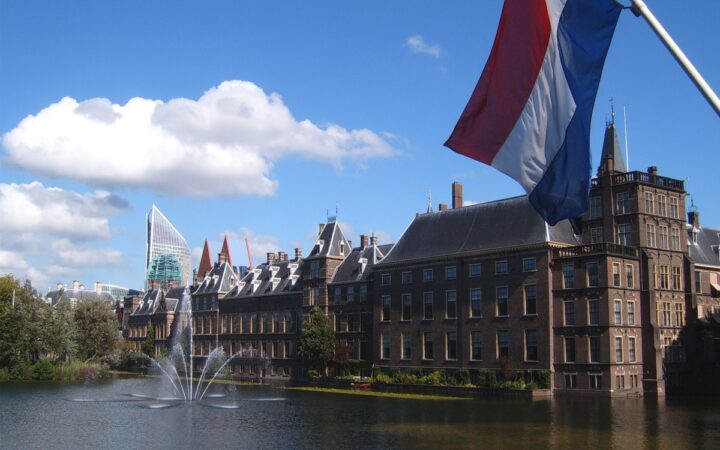
The Netherlands plans €3.5 billion in annual savings and roughly 25,000 fewer civil-service positions. AI is one lever, with specific targets due in 2027.
Nate Soares says he has not added to retirement savings for a decade over AI extinction fears. His personal forecast contrasts with Musk’s vision of abundance.
Thieves are targeting data-center deliveries through compromised freight accounts and reported attacks on escorts. Industry estimates put losses above $100 million.
Robert Martin’s ub-mode pairs engineering rules with complexity, duplication and mutation-testing tools to help AI coding agents produce maintainable code.
OpenAI and Anthropic claim AI-generated proofs refute the Exponential Time Hypothesis. Lean checks support the claims, while expert scrutiny remains essential.
Arthur Hayes wants FLOP to anchor a global market for AI compute, with futures for hedging and speculation. The network and token remain in development.
Goose pairs Wouter van Oortmerssen’s language design with an implementation largely written by Claude Fable. Carmack praised its memory model; benchmarks need context.
GPT-6.1 Terra targets visual reasoning and computer use at half Sol’s standard API rates, with access through ChatGPT Work, Codex and the API.
Cathedral says AI agents helped researchers access Anthropic’s internal data in under 12 hours. Anthropic says Claude chats, code and model weights were unaffected.