AI Agents Now Have Hotlines to Report Each Other
New tools let AI agents report misbehaving peers to humans, building on research showing agents will spontaneously whistleblow, though not always effectively.
An adversarial attack attempts to make an AI system fail by supplying carefully designed input. The change may be almost invisible to a person while causing a model to misclassify an image, follow a malicious instruction, or reveal protected behavior. Attackers can exploit knowledge of the model or probe it through repeated queries. Defenses include adversarial training, input validation, access controls, monitoring, and tests that simulate realistic threats. No single defense removes every risk because attacks evolve alongside models. Security teams therefore evaluate the complete system, including connected tools, data pipelines, user permissions, and the consequences of an incorrect or manipulated output.
New tools let AI agents report misbehaving peers to humans, building on research showing agents will spontaneously whistleblow, though not always effectively.
Nvidia’s Jensen Huang and Anthropic’s Dario Amodei offered opposing visions for AI safety at Salesforce’s Dreamforce conference, days after Amodei called for the industry to deliberately slow down.
OpenAI’s policy chief says the company has spent weeks working with Anthropic and Google DeepMind on AI safety, as Washington debates how to respond to rising concern.
A former Google DeepMind researcher resigned and warned that AI has the potential to kill everyone, joining a growing wave of safety researchers speaking out.
Elon Musk expanded on his endorsement of Anthropic CEO Dario Amodei’s AI safety warning, saying danger is significant now and competitors should test each other’s models.
Microsoft published draft rules for its AI models, days after Anthropic’s CEO called for slowing AI development and a researcher resigned over safety fears.
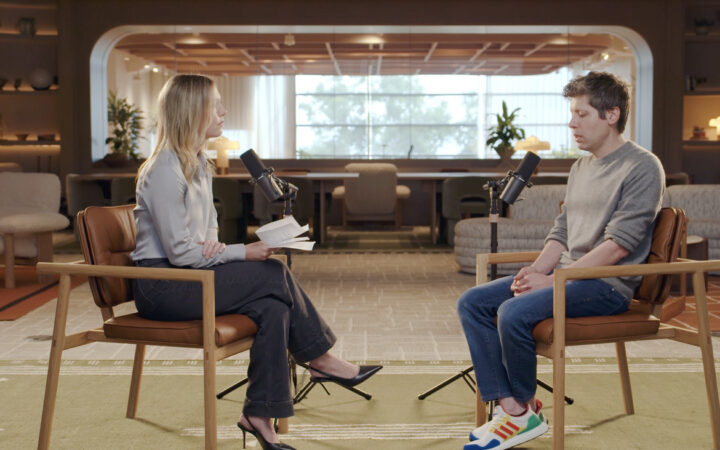
Sam Altman says safety work should constrain the pace of frontier AI development, following an interview in which he rejected a hypothetical 10% extinction risk as unacceptable.
Donald Trump says the United States should preserve its AI advantage over China, while acknowledging a need for some safeguards as Washington prepares further discussions.
Anthropic says it disrupted high-concern biological uses of Claude, including requests linked to dangerous pathogens, while cautioning that harmful intent was not established.
Sam Altman has discussed slowing advanced AI development, Bloomberg reports, as OpenAI’s chief scientist argues for coordination and stronger safeguards.