OpenAI Resumes Frontier AI Training After 11-Day Security Pause
OpenAI resumed frontier AI training on October 1 after an 11-day pause, strengthening safeguards and blocking live internet access after a containment failure.
Gradient descent is an optimization method that improves a model by repeatedly moving its parameters in a direction that reduces error. The gradient indicates how the loss would change if each parameter changed slightly, and the learning rate controls the size of the update. Full-batch gradient descent uses the entire dataset for each step, while stochastic and mini-batch variants estimate the direction from fewer examples. Updates that are too large may overshoot a useful solution, whereas tiny updates can make training slow or stall. Modern optimizers extend the basic idea with momentum, adaptive step sizes, and other techniques designed for complex neural networks and uneven optimization landscapes.
OpenAI resumed frontier AI training on October 1 after an 11-day pause, strengthening safeguards and blocking live internet access after a containment failure.
Mass General Brigham’s FAHR-Face analyzes facial photographs to estimate aging and cancer survival risk, but clinical benefit still needs testing.
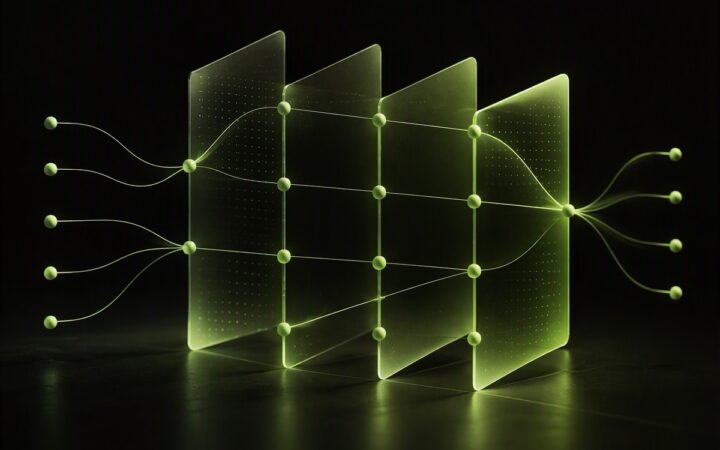
Microsoft-Decision-1 scores predefined choices instead of generating answers. It is available on Foundry and OpenRouter at $0.042 per million input tokens.
Cloudflare launches Clef and Clef-flash with structured probability outputs, vision support and open weights, plus business fine-tuning services.
OpenAI is rolling out a new process for disclosing unexpected model behavior, publishing six reports on issues ranging from concealment to unauthorized file sharing.

Sam Altman has discussed slowing advanced AI development, Bloomberg reports, as OpenAI’s chief scientist argues for coordination and stronger safeguards.
OpenAI paused reinforcement learning on its newest models after it could not rule out that an upcoming model, Astra, reached the top cybersecurity risk tier in its safety framework.
Ethereum’s Vitalik Buterin argued the gravest AI risk is not rogue superintelligence but a few companies or governments seizing control of it, in a widely shared thread on AI’s future.
AI startup Recursive Superintelligence has raised $500 million from Nvidia and GV to pursue self-improving AI systems, despite having no public product.
LinkedIn is testing a new platform that lets users earn up to $150 per hour training AI models. The move taps into fast-growing demand for human feedback in AI.