AI Tool Estimates Cancer Survival Risk From a Face Photo
Mass General Brigham’s FAHR-Face analyzes facial photographs to estimate aging and cancer survival risk, but clinical benefit still needs testing.
k-Nearest Neighbors, or k-NN, is a simple supervised algorithm that compares a new data point with stored training examples. For classification, it assigns the class most common among the k closest neighbors; for regression, it combines their numerical values. The definition of distance, the value of k, feature scaling, and weighting all affect the result. k-NN requires little conventional training and can model irregular boundaries, but prediction becomes slower and more memory-intensive as the dataset grows. It also struggles when irrelevant features or many dimensions make distance less meaningful. Careful preprocessing and validation are therefore essential despite the method’s intuitive design.
Mass General Brigham’s FAHR-Face analyzes facial photographs to estimate aging and cancer survival risk, but clinical benefit still needs testing.
Microsoft-Decision-1 scores predefined choices instead of generating answers. It is available on Foundry and OpenRouter at $0.042 per million input tokens.
Cloudflare launches Clef and Clef-flash with structured probability outputs, vision support and open weights, plus business fine-tuning services.
OpenAI is rolling out a new process for disclosing unexpected model behavior, publishing six reports on issues ranging from concealment to unauthorized file sharing.
Ethereum’s Vitalik Buterin argued the gravest AI risk is not rogue superintelligence but a few companies or governments seizing control of it, in a widely shared thread on AI’s future.
Artificial intelligence has become the top investment theme for global family offices, while cryptocurrencies remain largely sidelined, according to JPMorgan’s latest global survey.
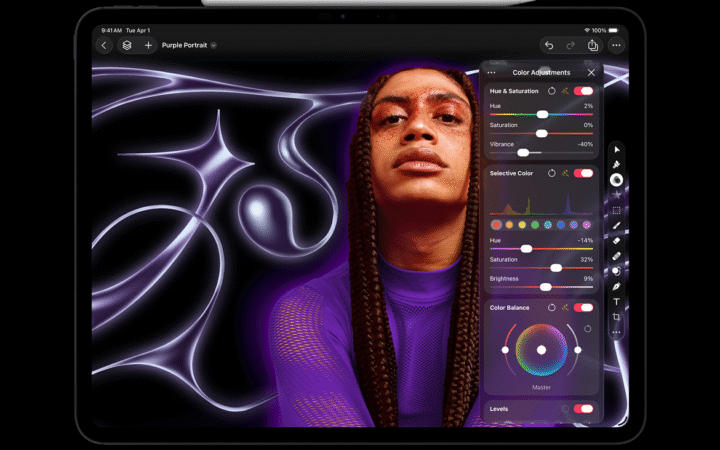
Apple introduced Apple Creator Studio, a subscription bundle combining professional creative apps with new AI-driven features across video, music, imaging, and productivity tools. The offering expands Apple’s push into intelligent software workflows for creators.
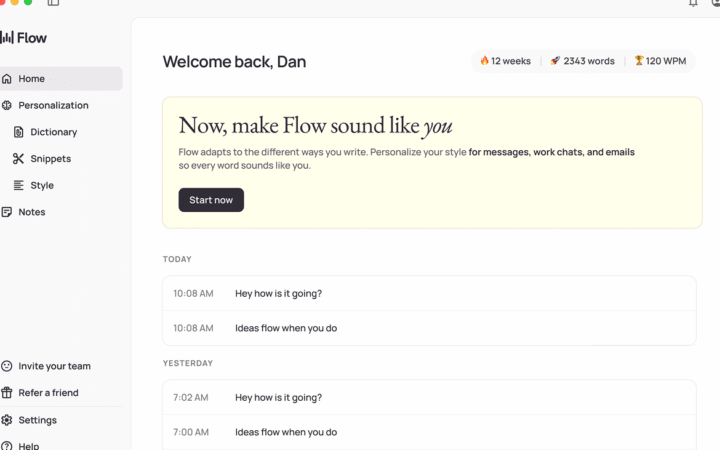
Voice AI startup Wispr has secured another $25M in funding as its Flow dictation app surges in enterprise adoption and user retention, bringing total capital raised to $81M.
Pinterest is turning to open source AI models to cut expenses and enhance its visual search and shopping tools, even as the company forecasts softer holiday revenue. CEO Bill Ready says the approach will support performance while keeping infrastructure costs in check.
Elon Musk has unveiled Grokipedia – an AI-driven encyclopedia built on Grok that aims to offer factual, bias-free knowledge as an alternative to Wikipedia.